Vals Raises US$40M to Become the Credit Rating Agency of AI Models
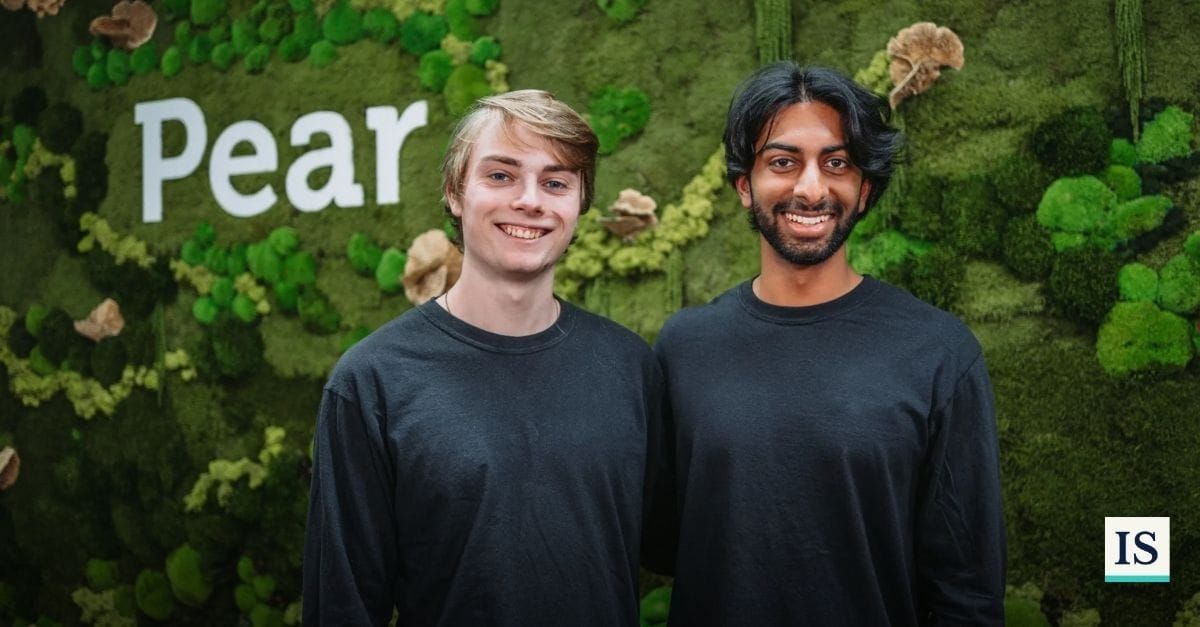
Vals, a San Francisco-based AI evaluation startup, raised a US$40 million Series A led by Andreessen Horowitz, announced in August 2026 and reported at a valuation of about US$400 million. Existing backers 8VC, Bloomberg Beta and Pear VC joined the round, along with new investors Hudson River Trading and NextLadder Ventures. The company was founded in 2024 by Stanford computer science classmates Rayan Krishnan, who serves as Chief Executive Officer, and Langston Nashold. Krishnan, 25, previously worked at Palantir, Microsoft and Stanford's AI lab.
Vals builds and runs benchmarks that measure how well AI models perform actual professional work rather than academic exams, covering law, finance, coding, cybersecurity, biosecurity and the law of armed conflict. Its core commercial argument is that it keeps test materials private, so model developers cannot train against the questions, and its business model mirrors standardized testing: labs pay Vals to sit the exam, much as students pay the College Board for the SAT. The company says revenue is running at eight times the prior year, that its customer base doubled in six months, and that headcount went from 8 people at the start of 2026 to 25 by September, with another 10 to 15 hires planned. Its product line now includes the Vals Index 2.0, the Smith coding benchmark, an RSI Index built with CoreWeave, and ReverseEngBench, a cybersecurity benchmark developed with Columbia University, Tufts, UC Berkeley and UCLA. Vals has also launched a program supplying model evaluations to federal agencies and has worked with the US Department of Commerce, members of Congress and NIST.
Market Context
The evaluation layer is the part of the AI stack that got built last. For three years the industry ran on public academic benchmarks that frontier models now saturate within months of release, and whose questions leak into training corpora. That left buyers reading scorecards produced and graded by the same companies selling the models. Andreessen Horowitz framed its investment around exactly that gap, comparing the opportunity to credit rating agencies and public-market auditors: when sellers know more than buyers and have every incentive to flatter themselves, independent measurement is what makes the market function.
Capital is arriving at that thesis quickly. In January 2026, LMArena raised US$150 million at a US$1.7 billion post-money valuation, led by Felicis and UC Investments with a16z also participating, on the back of a crowdsourced arena with more than five million monthly users and an enterprise product at roughly US$30 million in annualized consumption by the end of 2025. Vals is attacking the same problem from the opposite end: closed, domain-specific, expert-built tests instead of open public voting. That distinction matters because it defines two different products. LMArena sells scale and preference data; Vals sells the thing scale cannot produce, which is a test nobody has seen.
Key Signal
"We were seeing a bunch of new, very capable models come to market quickly, and the academic benchmarks [were] not keeping up with that frontier advance." — Rayan Krishnan, Co-Founder and CEO, Vals
Regional Relevance
For the United States, this is infrastructure for an industry that has spent enormous capital without an agreed measurement standard. American enterprises are deploying AI into regulated functions, including legal research, financial analysis, clinical support and security operations, where a procurement officer has to justify the choice of model to an auditor or a regulator. Vendor-reported benchmarks do not survive that conversation. An independent scorekeeper with private test sets is the mechanism that turns model selection from a vibes exercise into something closer to a documented decision, and the same logic explains why Vals is already feeding data to NIST and briefing Congress.
The federal angle carries the strategic weight. Washington has spent two years debating how to evaluate AI systems for government use without a neutral party capable of running the tests, and a private company that works with the Commerce Department and supplies benchmark data to NIST is positioning itself inside the policy apparatus, not merely alongside it. That is a durable commercial position and a contested one, since a private firm becoming the de facto national scorekeeper raises the question of who audits the auditor.
For the San Francisco Bay Area, the round continues a pattern of picks-and-shovels companies capturing value from a model race they do not compete in. Vals came out of the Stanford computer science pipeline, took early money from 8VC and Bloomberg Beta, and now counts a trading firm, Hudson River Trading, among its backers, which is a useful signal in itself: quantitative traders buy measurement systems when they believe the thing being measured is about to become an asset class.
The Other Side
Who verifies the verifier? The private test set is the product and the problem at once. Confidential benchmarks cannot be independently audited, which means the entire value proposition rests on trust in Vals as an institution rather than on inspectable methodology. Credit rating agencies had the same structure, and the 2008 record on how that ended is not encouraging. The question is what governance, disclosure or third-party review Vals adopts before, rather than after, a disputed score.
Does the payer distort the score? Labs pay Vals to be tested, which is the same conflict that sat underneath ratings agencies being paid by issuers. The company will argue that its reputation is its only asset and that a single compromised result destroys it. That argument is correct and it is also exactly what every conflicted intermediary has said.
How defensible is a benchmark? Vals retires its own tests as they saturate, which means the product must be rebuilt continuously. That is a services business wearing software margins, and it invites a structural question: at US$400 million on roughly 25 employees, the valuation assumes benchmarks become a standard others must license, not a consulting line item that large labs eventually bring in-house or that a well-funded rival such as LMArena bundles for free.
Sources & Transparency
- Vals, backed by Andreessen Horowitz, is looking to become the gold standard for AI benchmarking
- Investing in Vals
- Vals AI Raises $40M to Expand Independent AI Benchmarking
- Vals AI and Andreessen Horowitz Bet $40 Million on Confidential Benchmarking
- LMArena Raises $150 Million to Build the World's Most Trusted AI Evaluation Platform
- This Startup is Trying to Test How Well AI Models Actually Work